From Coarse to Nuanced: Cross-Modal Alignment of Fine-Grained Linguistic Cues and Visual Salient Regions for Dynamic Emotion Recognition
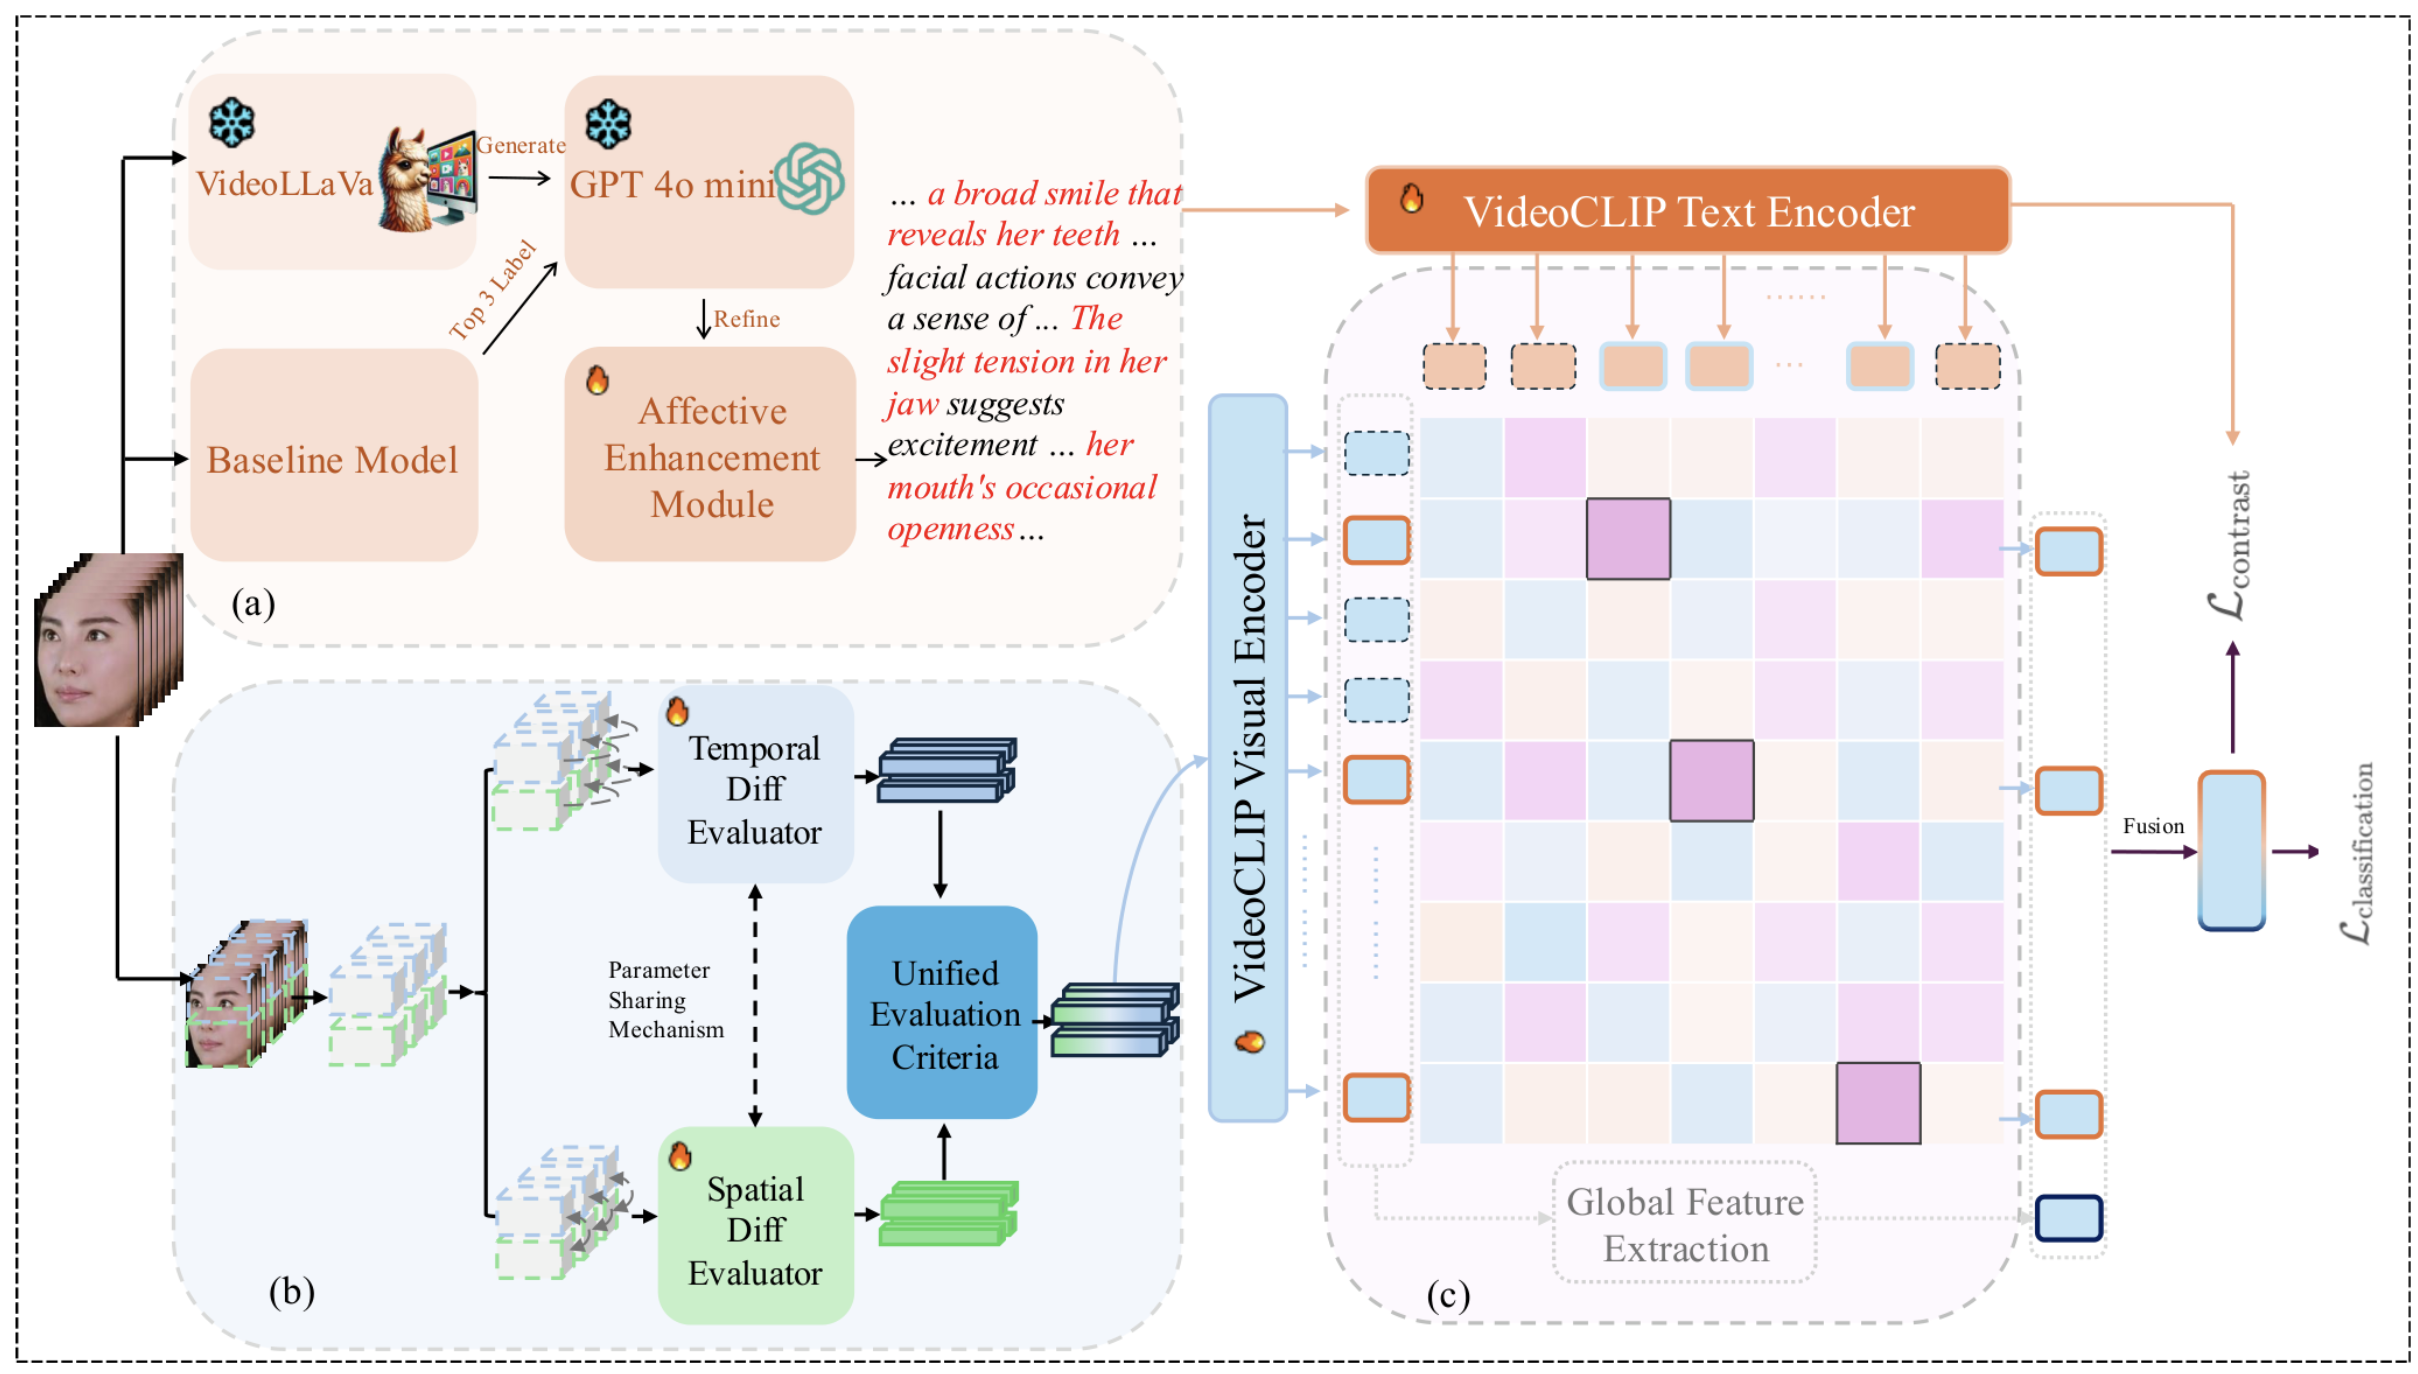
IEEE Transactions on Affective ComputingIntroduces GRACE for dynamic facial emotion recognition by aligning refined linguistic cues with salient facial dynamics, achieving state of the art on DFEW, FERV39k and MAFW.